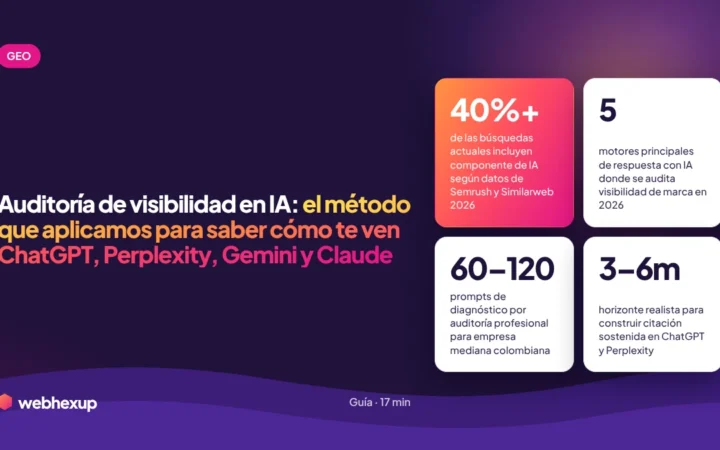

I’ve been doing technical SEO for Colombian and U.S. companies for nearly 20 years, and for the past 18 months, I’ve seen the same pattern repeat itself: clients who rank well on Google but disappear when their prospects ask ChatGPT. The typical reaction is, “But I’m #1 on Google,” and the technical answer is simple: Google and ChatGPT are different search engines with different retrieval logics. Ranking on Google is a necessary but not sufficient condition for appearing in ChatGPT Search.
This guide is the first in the “AI Positioning” series, in which I document how I currently work with clients who want to appear in ChatGPT, Perplexity, Claude, Gemini, and AI Overviews. This technical content is based on 10 verifiable sources and real-world work with clients in the real estate, e-commerce, healthcare, and B2B sectors in Colombia and the United States. If you need help implementing this on your site, check out our SEO, GEO, and AI Visibility services. For additional context, you can also read the guide on how to appear in Google AI Overviews and the guide to JSON-LD schema markup 2026.

Infographic summarizing the GEO system for appearing in ChatGPT Search. Download it, share it with your team, or embed it on your blog using the code below (we only ask that you keep the attribution link).
What is ChatGPT Search
and why should you care?
The context of 2026 makes this urgent for any business with a digital presence: Gartner predicts a 25% drop in traditional search volume by 2026, and at the same time, 60% of searches already end without a click (users who read the answer directly in the search engine without visiting the source site). Translation: the traffic that used to go to your website now stays on the Google, ChatGPT, or Perplexity interface, and only reaches your site if you’re the cited source.
The practical difference: three years ago, you were competing for a click from a list of 10 blue links. Today, you’re competing to be one of the 3–5 sources that AI cites in its summarized response. Clicks are rarer but much more valuable (users who have already read a summary of your content before arriving at your site).
An important context worth understanding from the outset: 85% of pages cited by ChatGPT also rank in Google’s organic top 10, but at the same time, 90% of ChatGPT citations come from pages that aren’t in Google’s top 20. This apparent contradiction is resolved by understanding that ChatGPT operates in two distinct modes: one favors traditional Google authority, and the other favors specific niche sources. We’ll return to this critical point in Section 9.
For Colombian companies, the opportunity is twofold: most competitors haven’t yet started optimizing for AIs (they’re focused exclusively on Google), so the first-mover advantage still holds. If you start now with a consistent GEO strategy, in 6–12 months your brand can become a go-to source for queries in your industry on ChatGPT and Perplexity, with a direct impact on lead generation.
How ChatGPT Search Works:
Retrieval Mode vs. Training Data Mode.
Retrieval mode: when ChatGPT searches in real time
It is activated when the question requires information that the model may not have up to date: “What is the best SEO agency in Medellín in 2026?”, “What is the price of an apartment in El Poblado?”, “What happened with Neuralink this week?”. ChatGPT performs a search via Bing, evaluates 5–15 sources, selects 2–4 to cite, and synthesizes the answer.
Changes you make to your site (new content, metadata optimization, schema updates) impact retrieval mode within weeks, not months. This is a huge competitive advantage over training data mode.
Training data mode: when ChatGPT responds from its memory
It’s triggered when the question is conceptual and doesn’t require up-to-date information: “What is schema markup?”, “How does Google’s algorithm work?”, “What is Answer-First Content Architecture?”. ChatGPT responds with content from its training data, without searching in real time. The data window varies depending on the model version (typically a 3–18-month lag).
Changes you make to your site today will impact training data mode in months or years, when OpenAI performs the next model retraining. It’s a much longer timeframe, but also more enduring: if you manage to get your brand included in the training data, you’ll appear in the responses until the next retraining.
The practical strategy I recommend: optimize your site for retrieval mode first (impact within weeks) and, in parallel, build off-page authority (editorial mentions, listicles, digital PR) to get included in the model’s next training data set. The two approaches reinforce each other.
How to tell which mode ChatGPT is using for your query
The clearest sign is whether ChatGPT displays source cards with links at the end of the response. If it does, it’s in retrieval mode. If it responds without citing specific sources or cites only generic references (“market studies,” “experts agree”), it’s in training data mode. Test your target queries this week and categorize them by mode to determine where to prioritize your efforts.
The equation: Bing + proprietary
index + authority signals.
Bing indexing is the non-negotiable prerequisite
If your site isn’t indexed by Bing, you can’t appear in ChatGPT Search in retrieval mode. It’s the same as not being on Google if you want to rank on Google: without the bare minimum, you’re out of the game. The steps:
- Verify in Bing Webmaster Tools that your site is correctly indexed and has no crawl errors
- Submit an XML sitemap to Bing (bing.com/webmasters) — yes, in addition to the one in Google Search Console
- Check IndexNow: the instant indexing protocol that Bing has adopted, which automatically notifies you of changes to your site
- Review the Bing Content Guidelines: Bing penalizes certain elements more severely than Google does—such as thin content or heavy JavaScript without server-side rendering
- Check for mobile-friendliness: Bing uses its own evaluator, not Google’s
OpenAI’s own crawling
OpenAI operates two main crawlers: OAI-SearchBot (for live ChatGPT Search) and GPTBot (for training data for the next model). Both must be able to access your site if you want to appear in ChatGPT. Check your robots.txt file:
The recommended configuration for 2026 is to explicitly allow OAI-SearchBot, GPTBot, ClaudeBot, PerplexityBot, and Google-Extended in your robots.txt (using Allow: /). Blocking these bots reduces your visibility in the corresponding AI systems, though it does not impact classic Google rankings. It’s a strategic decision: if your content is a unique business asset and you don’t want models to be trained on it, block them; if you want visibility in AI responses, allow them all.
Authority signals prioritized by LLMs
In addition to content, ChatGPT weighs authority signals such as editorial mentions in Tier 1 media outlets (Bloomberg, Reuters, Semana Empresas, Portafolio), consistent presence in vertical directories (Clutch, G2 for B2B; Google Business Profile for local; Trustpilot for consumer), active discussion on Reddit and Quora about your brand, and backlinks from .edu, .gov, and .org domains. Consistency matters more than quantity: 5 high-quality mentions over 6 months are worth more than 50 purchased backlinks in a single month.
Answer-First Content Architecture:
the key technique.
The exact pattern that works
For each H2 in your article or service page:
- Paragraph 1 (40–60 words): A complete, direct answer to the implicit question posed by the H2. No “in this article we’ll look at,” no “it’s important to understand that.” Go straight to the answer with the keyword bolded or at least with the main entity mentioned.
- Paragraphs 2–N: Elaboration with context, nuances, examples, case studies, counterexamples, and data. This is where you build subject matter authority and depth.
- Close with a transition to the next H2: a natural bridge that anticipates what’s coming next. This helps the LLM understand the relationship between sections.
Why it works: how an LLM reads
LLMs don’t read your content like a human. They break the text down into semantic chunks (usually blocks of 200–500 tokens) and evaluate each chunk based on its ability to answer specific queries. A chunk that begins with a direct and clear answer is 10 times more likely to be selected as a source than a chunk that starts with general context.
This is exactly the logic behind Google’s featured snippets, extended to all LLMs. It took Google years to refine the featured snippets algorithm; LLMs adopted this pattern from the start because it’s optimal for retrieval.
Practical Application in This Very Article
If you review this guide, you’ll see that each section begins with a block highlighted in lime green (what I call “answer-first blocks”) that answers the implicit question posed by the H2 heading in 40–60 words. This is the exact structure I recommend replicating. It’s no coincidence: this very article is optimized to be cited by ChatGPT when someone asks, “How do I appear in ChatGPT Search?”
Practical recommendation: Turn the first paragraph of each section in your existing articles into an “Answer-First” block. On sites where we’ve applied this technique for real clients, appearances in ChatGPT and Perplexity increased by 3x to 8x in 90 days. It’s the intervention with the best ROI in the entire GEO toolkit.
Entity SEO and semantic retrieval:
how the LLM chooses who to cite.
How to anchor entities in your content
- Schema Organization with complete sameAs: links to your company’s Wikipedia, LinkedIn, Twitter/X, YouTube, Instagram, and Crunchbase profiles. Each sameAs is a “coordinate” that helps the LLM determine that your brand is a specific entity and not a generic one.
- Schema Person with a verifiable byline: each author with a public LinkedIn profile, a specific job title, a “worksFor” property pointing to the organization, and “sameAs” links to professional networks.
- Explicitly mention related entities: In an article about WooCommerce SEO, mention “Rank Math,” “Yoast SEO,” “WP Rocket,” and “LiteSpeed Cache” by their full names. The LLM builds relationship graphs between these entities.
- Wikipedia and Wikidata: If your brand has an entry on Wikipedia or Wikidata, LLMs recognize it with extremely high confidence. This is difficult for young brands to achieve, but when applicable, it acts as a multiplier.
Semantic retrieval: how the LLM evaluates relevance
Semantic retrieval is the process by which the LLM compares the user’s query with embedding vectors from your content. LLMs maintain massive vector databases where each piece of content is represented by a high-dimensional mathematical vector (typically 1,536 dimensions in the case of OpenAI embeddings). When a query arrives, the LLM converts it into a vector and searches for the closest matching vectors.
To maximize your semantic ranking:
- Specific and detailed content: Vectors capture nuances. “Oversized 220g combed organic cotton T-shirt woven in Medellín” is semantically distinct and more specific than “T-shirt.”
- Rich context around entities: When you mention an entity, provide context around it (what it is, where it operates, what it’s related to)
- Terminological consistency: using the same technical terms as the industry (don’t invent tacky variations) improves your vector fit
This is the technical level that most agencies in Colombia haven’t reached yet. Those who master Entity SEO and semantic retrieval will have a measurable competitive advantage over the next 24 months, until these practices become standardized.
Off-page for AIs:
where you need to be mentioned.
Tier-1 Editorial Mentions
LLMs assign very high weights to mentions in reputable media outlets because they assume these have passed an editorial filter. An article in Portafolio that mentions your brand is worth more than 50 guest posts on average-quality blogs. The practical strategy:
- Create your own data stories or market reports to offer as an exclusive source to industry journalists
- Serve as an expert source for HARO (Help A Reporter Out), Qwoted, and similar platforms
- Publish opinion pieces (bylined columns) in niche media relevant to your industry
- Document case studies with verifiable data and share them with journalists covering your industry
Discussion platforms: Reddit, Quora, LinkedIn
ChatGPT and Perplexity heavily index Reddit and Quora. Authentic discussions about your brand in relevant subreddits or high-quality answers on Quora serve as signals of authority. The rule is authenticity over volume: 3 high-quality comments from your actual team in relevant subreddits are worth more than 30 generic comments.
LinkedIn is unique: publishing substantial technical content from the personal profiles of company leaders (not just from the page) is a strong signal for LLMs. Comments on those posts also feed into the training data for the next model.
Vertical directories that LLMs consume
For B2B: Clutch.co (agencies, consulting firms), G2.com (software), Capterra (SaaS), The Manifest (professional services). For consumer: Trustpilot, Google Business Profile, Yelp. For specific verticals: specialized niche sites (for real estate agencies in Colombia, Camacol; for dental clinics, the Colombian Dental Federation). Having a presence on 5–10 relevant directories with a complete profile and verified reviews makes a measurable difference.
Schema markup
prioritized by LLMs.
Prioritization by Industry
- Professional services firms (agencies, consulting firms, law firms, clinics): prioritize Organization + Person (founders and team) + Service (each service offered) + FAQPage per page
- E-commerce: Prioritize Product (with Offer, AggregateRating, Review, ShippingDetails) + Organization + BreadcrumbList per listing
- Real estate: RealEstateListing (per listing) + RealEstateAgent (headquarters and branches) + LocalBusiness (per physical branch)
- Media: NewsArticle + Author (with verification) + Publisher + BreadcrumbList
- Corporate blog: Article + Person (author) + Organization (publisher) + BreadcrumbList + FAQPage (where applicable)
Errors I See in 70% of Audits
- Schema Organization without `sameAs`: no links to social media, Wikipedia, or Crunchbase. The LLM cannot disambiguate your brand.
- Person schema with a generic jobTitle: “Consultant” instead of “WordPress SEO Consultant” or “Real Estate SEO Consultant.” Less specific = lower ranking in semantic retrieval.
- FAQPage automatically generated by Yoast/Rank Math without curated content: Low-quality FAQs do more harm than good. Opt for manually edited FAQs.
- Author schema without sameAs to LinkedIn: This is the primary E-E-A-T signal that LLMs value today.
To delve deeper into schema, the comprehensive schema markup guide—complete with JSON-LD 2026 types—covers the 12 active types with copy-and-paste examples.
How to measure your visibility
in ChatGPT Search.
The manual framework I use with clients
- Define 20–30 priority queries: a mix of transactional queries (“best SEO agency in Colombia”), informational queries (“what is Answer-First Architecture”), and navigational queries (“Webhexup reviews”).
- Test each query weekly on ChatGPT (with and without a login), Perplexity, and Google AI Overviews. Document the results in Google Sheets with the following columns: query, search engine, whether you appear (yes/no), position in the response, and quoted phrase.
- Sentiment tracking: When you appear, does the LLM cite you positively, neutrally, or with caveats? Sentiment matters just as much as presence.
- Competitive analysis: For queries where you don’t appear, who does? What do they have that you don’t? Reverse-engineer the cited content.
- Monthly iteration: Identify which content improves citation frequency and double down on it. Refactor content that isn’t gaining traction.
Emerging automated tools
The GEO tracking ecosystem is still immature but advancing rapidly. Tools I use or have evaluated in 2026:
- OmniSEO: multi-platform tracking (ChatGPT, Gemini, Perplexity), enterprise-focused
- SEOcrawl.ai: brand visibility dashboard for ChatGPT, Claude, Gemini, and Perplexity
- Semrush AI SEO Toolkit: newly launched in 2026, integrated with the Semrush suite
- Ahrefs Brand Radar: monitoring mentions in AI-generated content
- OpenAI/Anthropic proprietary APIs: for custom tracking with in-house automation
Practical recommendation: Start with manual tracking for the first 90 days to understand the patterns. Afterward, if the volume justifies it ($5K+ USD per month on tools), evaluate a commercial platform.
The 85% vs. 90% contradiction:
how to prioritize based on your industry.
What this means for your strategy
The honest conclusion is that you need to tackle both approaches simultaneously but with a different focus depending on your industry:
- Highly competitive, high-value verticals (SEO, marketing, consulting, financial services, healthcare): Prioritize classic authority content (Google top 10) because that’s where intensive retrieval mode comes into play
- Niche or long-tail verticals (specific tools, emerging techniques, new concepts): Prioritize specific, in-depth content even if it doesn’t reach the Google top 20, because LLMs need specific sources for niche answers
- Brands with a strong off-page presence: Prioritize building brand authority in “training data mode” (editorial mentions, discussions) because your brand is already citable—you just need to deepen trust
- New or unknown brands: Prioritize retrieval mode with Answer-First Architecture, because you need visible results within 4–12 weeks to fund operations
The rule I apply with clients: 60% of the effort goes toward classic optimization—which also benefits Google—and 40% toward GEO-specific techniques (Answer-First, semantic retrieval, qualitative off-page). This balance works because the two engines feed into each other: improving on Google also improves your performance on ChatGPT, and appearing on ChatGPT generates mentions that reinforce your Google rankings.
Common
mistakes when trying to appear on ChatGPT.
- Long introductions before answering: “In this article, we’ll look at…,” “It’s important to understand that before…”. LLMs skip these introductions and prefer pages that answer questions directly.
- Thin content without verifiable data: 800 words of generalities carry less weight than 400 words with 5 data points and cited sources. LLMs reward information density.
- Lack of Answer-First Architecture: the most common mistake. A good site with a classic structure loses citations to a mediocre site with a well-executed Answer-First approach.
- Accidentally blocking OAI-SearchBot in robots.txt: Check your file. If you have a generic
Disallow: /for User-agent: *, you’re also excluding AI bots. - Not being indexed by Bing: Without Bing indexing, you can’t appear in ChatGPT Search in retrieval mode. It’s a prerequisite.
- Content without anchored entities: You talk about “we” and “our service” without naming your specific brand or mentioning related entities. The LLM can’t figure out who you are.
- Zero qualitative off-page presence: Without editorial mentions or discussion on Reddit/Quora/LinkedIn, your brand lacks signals of authority for the LLM.
- Incomplete or poorly implemented Schema markup: Organization without `sameAs`, Person without `worksFor`, Article without a verified author. Each of these reduces your semantic ranking.
- Infrequent updates: LLMs prioritize recent content in retrieval mode. A 2022 article that hasn’t been updated will lose ranking in 2026.
- Ignoring negative sentiment: If ChatGPT mentions you but in a negative light (highlighting bad reviews), it’s worse than not appearing at all. Treat sentiment with the same seriousness as your presence.
The combination of these errors is what prevents most sites that want to appear in ChatGPT from gaining measurable traction within 6 months. Each individual error reduces the probability of being cited by 5–15%; collectively, they destroy any chance of appearing.
The essentials
in three paragraphs.
To appear in ChatGPT Search in 2026, you need three pillars executed in parallel: Answer-First Content Architecture with direct 40–60-word paragraphs at the beginning of each section in an inverted pyramid structure, clean Bing indexing with access granted to OAI-SearchBot and GPTBot in robots.txt (because 73% of ChatGPT Search results are identical to Bing’s), and high-quality off-page authority with editorial mentions in Tier 1 media outlets, discussions on Reddit and Quora, and a presence in relevant vertical directories.
ChatGPT operates in two distinct modes: retrieval mode (live web search with results appearing within weeks, triggered by current or specific queries) and training data mode (training data with results appearing within months, triggered by conceptual queries). 85% of cited pages also rank in Google’s organic top 10, but 90% of individual citations come from pages not in Google’s top 20, showing that both modes operate in parallel with complementary dynamics. The recommended strategy is 60% classic optimization that benefits both Google and ChatGPT simultaneously, and 40% GEO-specific techniques.
The most common mistakes are long introductions before answering, thin content without verifiable data, lack of an “Answer-First” architecture, entities not anchored via the Organization schema with a complete “sameAs” property and the Person schema with a specific “jobTitle,” sites not indexed by Bing, accidental blocking of the OAI-SearchBot in robots.txt, and a complete lack of high-quality off-page presence. With Gartner predicting a 25% decline in traditional search and 60% of searches ending without a click by 2026, the early-mover advantage in GEO remains valid for Colombian companies that launch within the next 12 months.
We answer your questions about
ChatGPT Search and GEO.
José Fernando Muñoz Álvarez
Digital consultant with nearly 20 years of experience in technical SEO, GEO (Generative Engine Optimization), AI Visibility, schema markup, Google Ads, and Meta Ads for Colombian and U.S. companies. Founder of Webhexup, an SEO-First agency in Medellín where he combines organic search, digital advertising, and visibility on ChatGPT, Perplexity, Claude, Gemini, and AI Overviews. He has audited and worked with over 300 websites using the same technical methodology documented in this guide. Previously, he was a co-founder of Eggs Blogs Casa Creativa and e-ideas Digital Agency. He shares real-world case studies and honest analyses on technical SEO, GEO, and AI Visibility on LinkedIn (jfmonin).